GenAI & LLMs · August 2026
Learning RAG from foundations to production
A practical, self-contained guide to modern RAG: context engineering, chunking, hybrid retrieval, reranking, GraphRAG, adaptive and agentic RAG, evaluation, and production operations.
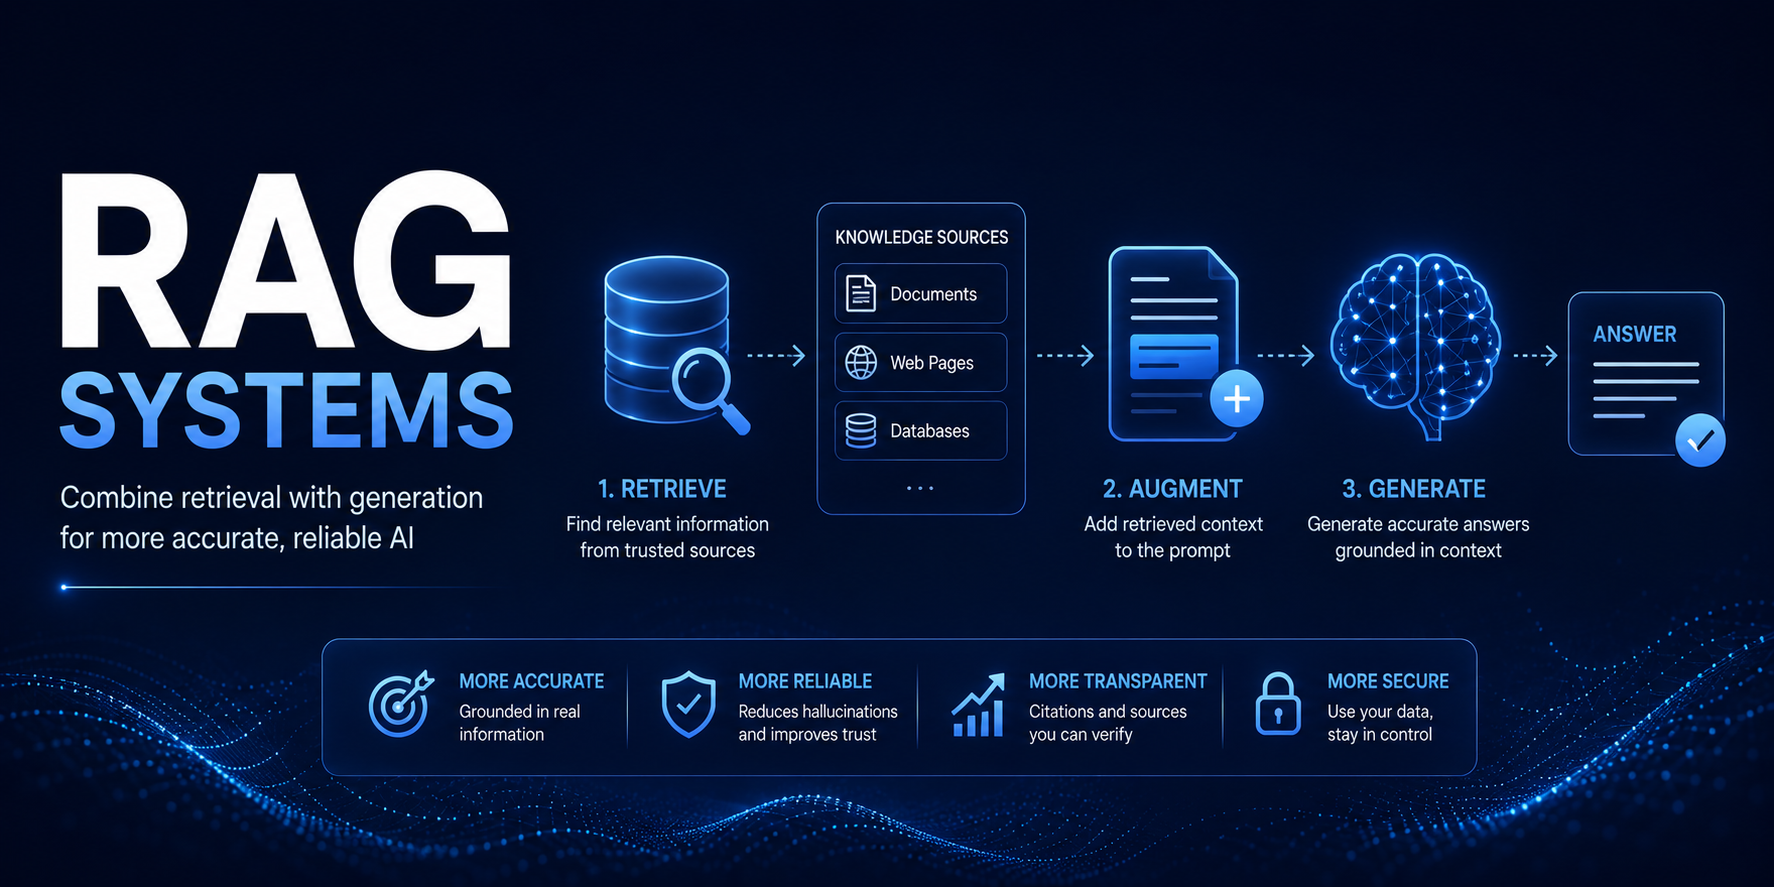
Retrieval-Augmented Generation has grown up. The classic demo diagram—documents → chunks → embeddings → vector database → top-k retrieval → LLM → answer—is still useful for learning the idea. It is not enough to describe a production system.
The hard part is not simply retrieving something. The hard part is consistently retrieving the right evidence for unpredictable questions, preserving enough context to interpret it, separating useful evidence from noise, constructing a prompt the model can use, generating a grounded response, and showing why the answer should be trusted.

Start with the problem RAG actually solves
Large language models contain enormous general knowledge, but that knowledge is encoded in model parameters. A model may not know your organization’s private documents, may be outdated, may generate plausible but unsupported details, and cannot be retrained every time a policy, product, contract, or procedure changes.
RAG changes the architecture. Instead of asking the model to remember everything, we give it access to an external knowledge layer at inference time. A useful mental model is: LLM = reasoning + generation and retrieval system = evidence. The objective is not to make the model “know more.” It is to give it the right evidence at the right time.
| Without RAG | With RAG |
|---|---|
| The model answers from parametric memory and the prompt. | The system retrieves current, governed evidence before generation. |
| Knowledge freshness depends on training data and prompt content. | Knowledge can update independently through the corpus and indexes. |
| Citations and provenance are difficult to prove. | Answers can cite retrieved sources when the pipeline preserves provenance. |
| Private domain knowledge must be pasted into context or fine-tuned. | Private knowledge can remain in controlled stores with access filters. |
RAG has two pipelines, not one
A production RAG system has an offline knowledge pipeline and an online answer pipeline. The offline pipeline prepares the knowledge layer: collect documents, parse formats, clean text, preserve structure, split into retrievable units, enrich metadata, create embeddings, build lexical or graph indexes, and keep the corpus fresh. The online pipeline handles the question: analyze the query, retrieve candidates, rerank evidence, construct context, generate the answer, cite sources, and evaluate behavior.

Chunking is about preserving meaning
One of the first implementation questions is usually “what chunk size should we use?” But fixed token size is not the real design problem. The real question is: what is the smallest retrievable unit that still preserves enough meaning to answer correctly?
A chunk that says “It increased by 14% compared with the previous reporting period” may be valid text but terrible evidence. What increased? Which product? Which region? Which reporting period? The information may have existed in the source document, but naive chunking destroyed the context required to interpret it.

- Structural chunking: preserve headings, sections, paragraphs, tables, captions, and document hierarchy.
- Semantic chunking: split where meaning changes instead of cutting at arbitrary token boundaries.
- Parent-child retrieval: retrieve small chunks but return the larger parent section for generation.
- Contextual retrieval: attach brief source-aware context to each chunk before embedding and lexical indexing.
- Metadata-aware indexing: preserve source, date, author, department, access class, version, and document type.
Semantic similarity is not the same as relevance
Embeddings are powerful because they make semantic search possible. A user can ask “How do employees take parental leave?” and retrieve a section titled “Family Leave Policy.” That is exactly where dense retrieval shines.
But semantic similarity is not always relevance. Error codes, policy IDs, invoice numbers, product SKUs, exact names, and legal clauses often need lexical matching. A query like “AX-774-B” or “connection reset error 104” may be better served by keyword search or metadata filtering than embeddings alone.

The retrieval stack
Embeddings capture meaning and paraphrase, but may miss exact identifiers.
BM25 and lexical search are strong for names, codes, policy IDs, and rare terms.
Source, version, date, owner, jurisdiction, and access class prevent bad candidates.
A stronger relevance model narrows broad candidates to the passages that answer.
The context builder controls order, diversity, citations, and evidence density.
A good system can say the evidence is insufficient instead of improvising.
Retrieval finds candidates; reranking finds evidence
A practical system often retrieves broadly and reranks precisely. Stage one may retrieve 20 to 100 plausible candidates quickly. Stage two uses a stronger model or cross-encoder-style relevance check to decide which passages actually answer the question. Retrieval optimizes recall; reranking optimizes precision.
This distinction makes debugging much easier. If the right passage is not in the candidate set, improve ingestion, chunking, embeddings, lexical search, query transformation, or filters. If the right passage is retrieved but not selected, improve ranking, fusion, diversity, or reranking. If the right passage reaches the model but the answer is wrong, improve context construction, prompting, citation rules, or abstention behavior.
The user’s question may be the retrieval problem
Users do not write search-engine-friendly queries. They ask conversational, ambiguous, incomplete, or multi-part questions: “What happened with that policy we discussed?” “Why was it rejected?” “Compare our 2025 European revenue with North America and explain the main reasons.” A production system often needs to transform the request before retrieval.

- Query rewriting: convert conversational language into a retrieval-oriented query.
- Query expansion: add related terms, acronyms, synonyms, and domain vocabulary.
- Multi-query retrieval: search several plausible interpretations and fuse candidates.
- Query decomposition: split complex questions into subquestions and retrieve separately.
- Source routing: choose vector, keyword, graph, SQL, web, or tool retrieval based on the task.
GraphRAG and structured retrieval: when relationships matter
Vector retrieval works well when the answer lives in a few relevant passages. Some questions are different. They ask about relationships among people, companies, projects, regulations, contracts, events, risks, and technologies. No single paragraph may contain the answer; the answer emerges from connected evidence.
Graph-based retrieval is useful when entities and relationships carry meaning: “Which technologies connect the projects associated with organizations affected by this regulation?” A graph can expose relationships that are difficult to retrieve with passage similarity alone. GraphRAG is not a replacement for vector retrieval; it is another retrieval primitive for relationship-heavy questions.
Long-context models did not kill RAG
Large context windows changed the design space. For a small, stable corpus, putting more information directly into context can be simpler than building a complex retrieval system. But long context does not eliminate cost, latency, access control, freshness, provenance, irrelevant information, and very large knowledge bases.
| Question | Long context may be enough when… | RAG is usually better when… |
|---|---|---|
| Corpus size | The corpus is small enough to fit and cheap enough to send. | The corpus is large, distributed, or changes frequently. |
| Freshness | Documents are stable during the session. | Policies, products, tickets, records, or data change continuously. |
| Governance | Everyone can see the same context. | Users have different permissions, regions, contracts, or data boundaries. |
| Traceability | Source provenance is less important. | The answer must cite evidence and support audit or review. |
| Complexity | A simpler baseline meets quality and cost targets. | Evidence selection materially improves quality, latency, cost, or safety. |
Adaptive and agentic RAG
Traditional RAG retrieves for every question. Adaptive RAG first decides whether retrieval is needed. “Rewrite this sentence” may not need retrieval. “What is our parental leave policy?” does. “Compare our policy with provincial legislation” may require multiple sources, decomposition, and review.
Agentic RAG takes this further: retrieval becomes a loop. The system can plan, choose tools, search, inspect evidence, decide whether evidence is sufficient, reformulate the query, retrieve again, verify, and then answer. This is powerful for complex tasks, but it also introduces new risks: cascading errors, retrieval misalignment, memory poisoning, tool misuse, cost drift, and harder evaluation.

Evaluate the pipeline, not only the answer
A RAG system can produce a fluent answer while retrieving weak evidence. It can retrieve excellent evidence and still generate a bad answer. It can cite sources that were retrieved but do not actually support the claim. A single “answer quality” score hides the failure mode.

| Layer | What to measure | Typical failure signal |
|---|---|---|
| Corpus and ingestion | Parsing quality, freshness, duplicates, permissions, metadata coverage. | The right information exists but is not searchable or current. |
| Retrieval | Recall, precision, rank, diversity, filter correctness, empty retrieval. | The needed evidence never reaches the model. |
| Context construction | Evidence density, ordering, citation mapping, token budget use. | Good evidence is retrieved but buried or fragmented. |
| Generation | Faithfulness, completeness, abstention, citation support, clarity. | The model ignores evidence or overstates unsupported claims. |
| Operations | Latency, cost, drift, incidents, access denials, user corrections. | The system works in tests but fails under real usage conditions. |
What state-of-the-art RAG looks like now
The field has moved from naive RAG toward modular, context-aware, adaptive, structured, and agentic systems. But complexity is not automatically progress. A simple document-structure-preserving retrieve-then-read baseline can beat a sophisticated architecture if the complex system is poorly matched to the workload. Add complexity only when evaluation shows the baseline failure clearly.

A practical learning roadmap
The Awesome RAG training follows a build-evaluate-improve rhythm. Start with foundations, embeddings, chunking, vector search, metadata filtering, hybrid retrieval, reranking, query transformation, context engineering, and evaluation. Then move into production architecture, graph or structured retrieval, adaptive RAG, multimodal retrieval, corrective RAG, and agentic RAG.
- Beginner: build a local cited RAG assistant and understand retrieval, chunks, embeddings, and citations.
- Intermediate: compare hybrid search, metadata filtering, reranking, query rewriting, and RAG evaluation.
- Advanced: study GraphRAG, corrective RAG, multimodal retrieval, adaptive routing, agentic RAG, and production operations.
- Production habit: build a baseline, evaluate failures, add one capability, then prove the improvement.
Explore the course and test your understanding
The repository and Learning Hub provide a guided curriculum, practical labs, notebooks, examples, and quizzes. Use the course as a self-directed path, a workshop companion, or a starting point for building internal RAG capability.
Explore the Awesome RAG repository ↗
Open the RAG Learning Hub, labs, and quizzes ↗
References and further reading
Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks ↗
The foundational RAG paper introducing retrieval-augmented generation for knowledge-intensive tasks.
Retrieval-Augmented Generation for Large Language Models: A Survey ↗
A widely cited survey organizing RAG into naive, advanced, and modular patterns, with discussion of indexing, retrieval, generation, and evaluation.
Anthropic: Introducing Contextual Retrieval ↗
Practical guidance on contextualized chunks and combining embeddings with BM25 to reduce context loss during retrieval.
From Local to Global: A Graph RAG Approach to Query-Focused Summarization ↗
Microsoft Research paper introducing GraphRAG for reasoning over relationships and global questions across a corpus.
RAGAS: Automated Evaluation of Retrieval Augmented Generation ↗
Evaluation framework separating faithfulness, answer relevance, context relevance, and context recall for RAG systems.
Self-RAG: Learning to Retrieve, Generate, and Critique ↗
Research on models that decide when to retrieve and critique their own retrieved evidence and generated responses.
Corrective Retrieval Augmented Generation ↗
A corrective RAG approach that evaluates retrieved documents and triggers correction strategies when retrieval quality is weak.
A Survey of Agentic Retrieval-Augmented Generation ↗
Survey of agentic RAG systems where planning, retrieval orchestration, memory, and tool use turn retrieval into a sequential decision process.